EN

Java7 HashMap 源码分析

字数统计: 4.4k阅读时长: 19 min
2015/08/05
loading

在没有排序或额外索引的数组、链表中,按值查找最坏需要遍历全部元素。哈希表(hash table)通过哈希值定位桶,在哈希分布良好时,基本查找可以接近常数时间;这不代表所有输入下都能保证 O(1)。

HashMap是基于哈希表的 Map 接口的实现。此实现提供所有可选的映射操作,并允许使用 null 值和 null 键。(除了非同步和允许使用 null 之外,HashMap 类与 Hashtable 大致相同。)此类不保证映射的顺序,特别是它不保证该顺序恒久不变。

本文按源码顺序看 HashMap:数组与链表的数据结构、构造函数、put 和扩容、get,最后是迭代器如何用 modCount 检查结构修改。末尾补充后续 JDK 的变化。

版本说明(2026-10-13 核查):本文保留 2015 年的历史源码分析,以下实现按 OpenJDK jdk7u21-b11 核对。构造时分配数组、Entry 链表和备用哈希等细节已不适用于所有后续版本,连 Java 7 的更新版也有差异。源码片段用于阅读 JDK 内部实现,不是可直接复制运行的独立类;Android 的实现也需按对应系统的 libcore 源码核对。

1. HashMap的数据结构:

这个版本的 HashMap 使用数组和链表:数组保存各个桶的链表头,空桶为 null。下面先列出 Entry 的字段,方法见链接中的完整源码。
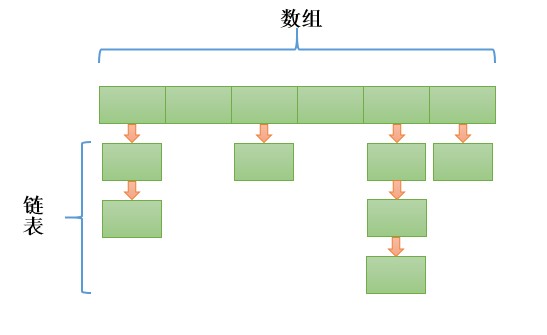
HashMap 的数组与链表结构

1
2
3
4
5
6
7
static class Entry<K,V> implements Map.Entry<K,V> {
final K key;
V value;
Entry<K,V> next;
int hash;
// Methods omitted; see the linked source.
}

Entry 是 HashMap 中包级私有的静态嵌套类,实现 Map.Entry<K,V>,next 指向下一个节点。key 引用是 final,不等于 key 对象不可变;作为键存入后,不应修改会影响其 hashCode() 或 equals() 的状态。

2.构造函数

HashMap的构造函数有四个:

  1. HashMap() — 构造一个具有默认初始容量 (16) 和默认加载因子 (0.75) 的空 HashMap。
  2. HashMap(int initialCapacity) — 构造一个带指定初始容量和默认加载因子 (0.75) 的空 HashMap。
  3. HashMap(int initialCapacity, float loadFactor) — 构造一个带指定初始容量和加载因子的空 HashMap。
  4. HashMap(Map<? extends K,? extends V> m) — 构造一个映射关系与指定 Map 相同的新 HashMap

就两种,一个是指定初始容量和加载因子,一个是用一个给定的映射关系生成一个新的HashMap。说一下第一种。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
/**
* Constructs an empty <tt>HashMap </tt> with the specified initial
* capacity and load factor.
*
* @param initialCapacity the initial capacity
* @param loadFactor the load factor
* @throws IllegalArgumentException if the initial capacity is negative
* or the load factor is nonpositive
*/
public HashMap( int initialCapacity, float loadFactor) {
if (initialCapacity < 0)
throw new IllegalArgumentException( "Illegal initial capacity: " +
initialCapacity);
if (initialCapacity > MAXIMUM_CAPACITY)
initialCapacity = MAXIMUM_CAPACITY;
if (loadFactor <= 0 || Float.isNaN(loadFactor))
throw new IllegalArgumentException( "Illegal load factor: " +
loadFactor);

// Find a power of 2 >= initialCapacity
int capacity = 1;
while (capacity < initialCapacity)
capacity <<= 1;

this.loadFactor = loadFactor;
threshold = (int)Math.min(capacity * loadFactor, MAXIMUM_CAPACITY + 1);
table = new Entry[capacity];
useAltHashing = sun.misc.VM.isBooted() &&
(capacity >= Holder.ALTERNATIVE_HASHING_THRESHOLD);
init();
}

initialCapacity 是请求的初始桶数,不是可无扩容容纳的键值对数量。此版本在构造时分配数组:负数被拒绝,超过 MAXIMUM_CAPACITY 的请求先被截到 1 << 30,然后取不小于请求值的最小 2 的幂;请求 0 时数组长度为 1。默认容量为 16,默认加载因子为 0.75。

构造时按 capacity * loadFactor 等表达式计算 threshold,但不能把 (1 << 30) + 1 当成整个生命周期的阈值上限:resize 到达最大容量后会改设为 Integer.MAX_VALUE。1 << 30 也只是实现允许的桶数上限,不保证实际堆内存能分配这么大的数组。

下面的 addEntry 只有在新增键、插入前 size >= threshold,且目标桶非空时才调用扩容。因此不能简化成“数量一到阈值就立刻扩容”。

当加载因子小于等于 0,或者为 NaN 时,构造函数会抛出 IllegalArgumentException。NaN 是浮点类型中的特殊值。

3.put操作

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
/**
* Associates the specified value with the specified key in this map.
* If the map previously contained a mapping for the key, the old
* value is replaced.
*
* @param key key with which the specified value is to be associated
* @param value value to be associated with the specified key
* @return the previous value associated with <tt>key </tt>, or
* <tt>null </tt> if there was no mapping for <tt> key</tt> .
* (A <tt>null </tt> return can also indicate that the map
* previously associated <tt>null </tt> with <tt> key</tt> .)
*/
public V put(K key, V value) {
if (key == null)
return putForNullKey(value);
int hash = hash(key);
int i = indexFor(hash, table.length );
for (Entry<K,V> e = table[i]; e != null; e = e.next) {
Object k;
if (e.hash == hash && ((k = e.key) == key || key.equals(k))) {
V oldValue = e.value;
e.value = value;
e.recordAccess( this);
return oldValue;
}
}

modCount++;
addEntry(hash, key, value, i);
return null;
}

HashMap 允许 null 键,也允许 null 值。put 先判断 key 是否为 null,是则走专门的处理路径。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
/**
* Offloaded version of put for null keys
*/
private V putForNullKey(V value) {
for (Entry<K,V> e = table[0]; e != null; e = e.next) {
if (e.key == null) {
V oldValue = e.value;
e.value = value;
e.recordAccess( this);
return oldValue;
}
}
modCount++;
addEntry(0, null, value, 0);
return null;
}

null 键位于 table[0] 的链表中;只有找到 key 为 null 的节点才替换其 value,否则新增节点。并不是只要第一个桶非空就替换它。稍后会看到 addEntry 函数。

PS:null 键放在 table[0],为什么还要遍历这条链表?

回到 put:key 非空时先调用 hash(key)。这里不仅使用 key 的 hashCode(),还会混合高位与低位;启用备用哈希时另有种子和 String 专用路径。补上这个版本的完整方法:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
final int hash(Object k) {
int h = 0;
if (useAltHashing) {
if (k instanceof String) {
return sun.misc.Hashing.stringHash32((String) k);
}
h = hashSeed;
}

h ^= k.hashCode();

// This function ensures that hashCodes that differ only by
// constant multiples at each bit position have a bounded
// number of collisions (approximately 8 at default load factor).
h ^= (h >>> 20) ^ (h >>> 12);
return h ^ (h >>> 7) ^ (h >>> 4);
}

useAltHashing、hashSeed 和 sun.misc.Hashing 属于此版本的内部实现,不是应用代码应调用的公共 API。此标签的备用哈希默认阈值为 Integer.MAX_VALUE,不能假定一般 map 已启用该分支。得到哈希值后,indexFor 决定桶下标:

1
2
3
4
5
6
/**
* Returns index for hash code h.
*/
static int indexFor (int h, int length) {
return h & (length-1);
}

indexFor 虽然只有一行,写得却很巧妙。还记得前面数组长度的限制吗?length 是正的 2 的幂,length - 1 的低位全是 1,按位与便能取出这些低位,得到 0 到 length - 1 的下标。不能不加条件地把它等同于 Java 的 h % length:h 为负数时,% 的结果可能为负,而这里的下标不会。若长度不是 2 的幂,这个掩码也不能均匀覆盖所有桶。是否更快则要看具体运行时,不能仅凭运算符作性能承诺。

前面的问题在这里就有答案了。因为indexFor函数返回值的范围是0到(length-1),所以可能会有key值不是null的Entry存到table[0]中,所以前面还是需要遍历链表的。

得到桶下标后遍历链表:哈希值相同仍不代表 key 相等,还要比较对象身份或 equals()。找到已有 key 就替换 value 并返回旧值,这条路径不会执行 modCount++。只有没找到 key、准备新增映射时,才增加结构修改计数并调用 addEntry。后面的 fail-fast 就用到这个计数。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
/**
* Adds a new entry with the specified key, value and hash code to
* the specified bucket. It is the responsibility of this
* method to resize the table if appropriate.
*
* Subclass overrides this to alter the behavior of put method.
*/
void addEntry (int hash, K key, V value, int bucketIndex) {
if ((size >= threshold) && ( null != table[bucketIndex])) {
resize(2 * table.length);
hash = ( null != key) ? hash(key) : 0;
bucketIndex = indexFor(hash, table.length);
}

createEntry(hash, key, value, bucketIndex);
}

addEntry 接收 hash、key、value 和桶下标,最后一个参数来自 indexFor(hash, table.length),不是传入 table.length - 1。只有 size >= threshold 且目标桶非空时才尝试把容量翻倍;目标桶为空时,新增节点不会延长已有链表,因此这个版本可以推迟扩容。扩容后会重新计算当前待插入键的 hash 和桶下标,再调用 createEntry。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
/**
* Rehashes the contents of this map into a new array with a
* larger capacity. This method is called automatically when the
* number of keys in this map reaches its threshold.
*
* If current capacity is MAXIMUM_CAPACITY, this method does not
* resize the map, but sets threshold to Integer.MAX_VALUE.
* This has the effect of preventing future calls.
*
* @param newCapacity the new capacity, MUST be a power of two;
* must be greater than current capacity unless current
* capacity is MAXIMUM_CAPACITY (in which case value
* is irrelevant).
*/
void resize(int newCapacity) {
Entry[] oldTable = table;
int oldCapacity = oldTable.length;
if (oldCapacity == MAXIMUM_CAPACITY) {
threshold = Integer.MAX_VALUE;
return;
}

Entry[] newTable = new Entry[newCapacity];
boolean oldAltHashing = useAltHashing;
useAltHashing |= sun.misc.VM.isBooted() &&
(newCapacity >= Holder.ALTERNATIVE_HASHING_THRESHOLD);
boolean rehash = oldAltHashing ^ useAltHashing;
transfer(newTable, rehash);
table = newTable;
threshold = (int)Math.min(newCapacity * loadFactor , MAXIMUM_CAPACITY + 1);
}

resize 先检查是否已到最大容量 1 << 30。到达后只把阈值设为 Integer.MAX_VALUE,不再扩大数组。否则,在这里的 addEntry 调用路径上创建容量翻倍的新数组;由于原容量是 2 的幂且不超过上限,翻倍不会越过该上限。接着调用 transfer 迁移已有节点。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
/**
* Transfers all entries from current table to newTable.
*/
void transfer(Entry[] newTable, boolean rehash) {
int newCapacity = newTable.length;
for (Entry<K,V> e : table) {
while( null != e) {
Entry<K,V> next = e.next;
if ( rehash) {
e.hash = null == e.key ? 0 : hash(e.key);
}
int i = indexFor(e.hash, newCapacity);
e.next = newTable[i];
newTable[i] = e;
e = next;
}
}
}

transfer 把旧节点迁移到新数组。如果扩容时备用哈希从关闭变为开启,rehash 才为 true,已有非空 key 才会重新调用 hash(key);否则使用节点缓存的 hash 计算新下标。

容量翻倍不代表每个节点都会换桶:hash 不变时,新下标要么仍是旧下标,要么是旧下标加旧容量。这里采用头插法,迁移过程中可能反转同一链表中的节点次序。回到 resize 后再替换 table 并更新阈值。无论是否扩容,应用都不应依赖 HashMap 的迭代顺序。

按预期数据规模设置容量可以减少迁移,但盲目放大也会增加内存和遍历成本;遍历要扫描桶数组及节点,不只取决于 size。

回到函数addEntry 中,判断完是不是需要resize后就需要创建一个新的Entry了。

1
2
3
4
5
6
7
8
9
10
11
12
13
/**
* Like addEntry except that this version is used when creating entries
* as part of Map construction or "pseudo -construction" (cloning,
* deserialization). This version needn't worry about resizing the table.
*
* Subclass overrides this to alter the behavior of HashMap(Map),
* clone, and readObject.
*/
void createEntry( int hash, K key, V value, int bucketIndex) {
Entry<K,V> e = table[bucketIndex];
table[bucketIndex] = new Entry<>(hash, key, value, e);
size++;
}

调用createEntry函数,参数跟addEntry一样,第一个是key的hash值,第二个第三个分别是key和value,最后一个是这个key在table中的位置。这里的操作与Entry的构造函数有关系。

1
2
3
4
5
6
7
8
9
/**
* Creates new entry.
*/
Entry (int h, K k, V v, Entry<K,V> n) {
value = v;
next = n;
key = k;
hash = h;
}

构造函数中传入一个Entry对象,并把它当做这个新生成的Entry的next。所以createEntry函数中的操作相当于把table[bucketIndex]上的链表拿下来,放在新的Entry后面,然后再把新的Entry放到table[bucketIndex]上。
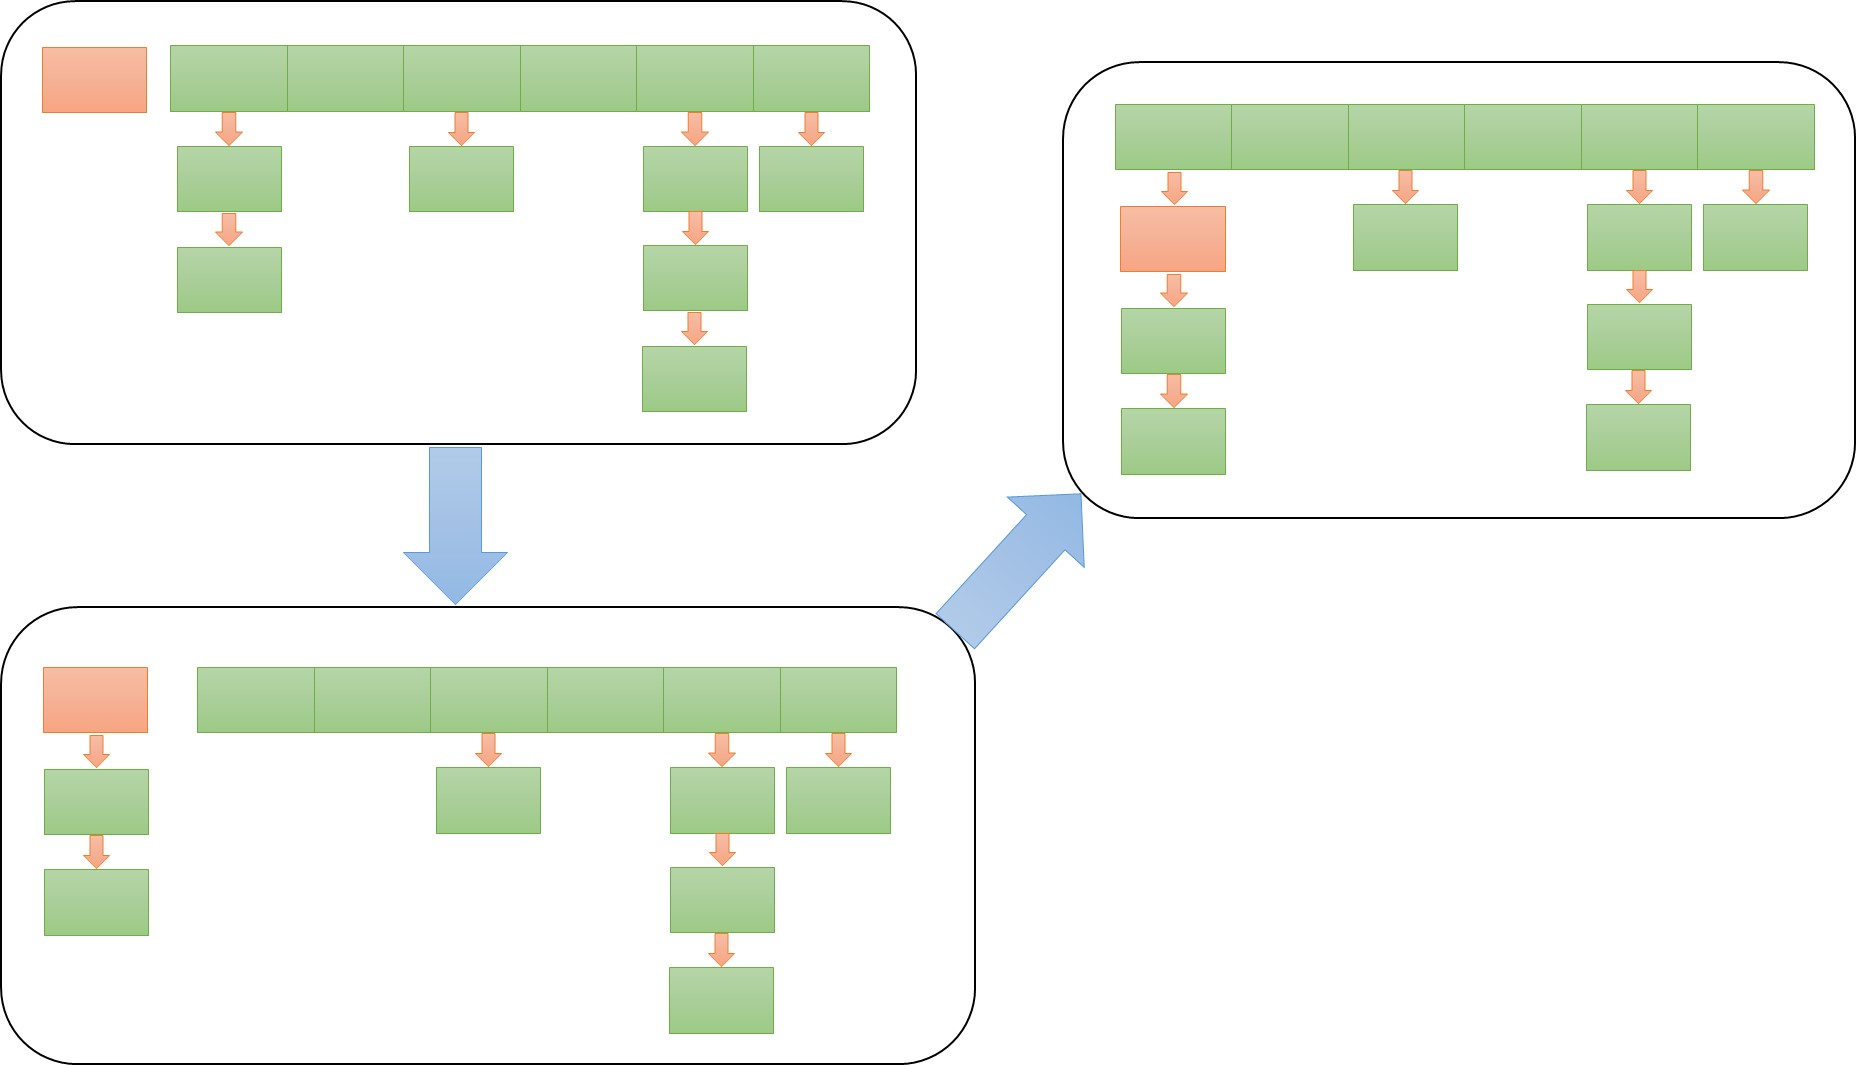
新 Entry 插入链表头部

到这里整个put函数算是结束了。如果新插入的K,V则会返回null。

4.get操作

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
/**
* Returns the value to which the specified key is mapped,
* or {@code null} if this map contains no mapping for the key.
*
* <p>More formally, if this map contains a mapping from a key
* {@code k} to a value {@code v} such that {@code (key==null ? k==null :
* key.equals(k))}, then this method returns {@code v}; otherwise
* it returns {@code null}. (There can be at most one such mapping.)
*
* <p>A return value of {@code null} does not <i>necessarily </i>
* indicate that the map contains no mapping for the key; it's also
* possible that the map explicitly maps the key to {@code null}.
* The {@link #containsKey containsKey} operation may be used to
* distinguish these two cases.
*
* @see #put(Object, Object)
*/
public V get(Object key) {
if (key == null)
return getForNullKey();
Entry<K,V> entry = getEntry(key);

return null == entry ? null : entry.getValue();
}

也是先判断key是不是null,做特殊处理。直接上代码,不赘述。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
/**
* Offloaded version of get() to look up null keys. Null keys map
* to index 0. This null case is split out into separate methods
* for the sake of performance in the two most commonly used
* operations (get and put), but incorporated with conditionals in
* others.
*/
private V getForNullKey() {
for (Entry<K,V> e = table[0]; e != null; e = e.next) {
if (e.key == null)
return e.value;
}
return null;
}

key不是null则会调用getEntry函数,并返回一个Entry对象,如果不是null,就返回entry的value。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
/**
* Returns the entry associated with the specified key in the
* HashMap. Returns null if the HashMap contains no mapping
* for the key.
*/
final Entry<K,V> getEntry(Object key) {
int hash = (key == null) ? 0 : hash(key);
for (Entry<K,V> e = table[ indexFor(hash, table.length)];
e != null;
e = e.next) {
Object k;
if (e.hash == hash &&
((k = e.key) == key || (key != null && key.equals(k))))
return e;
}
return null;
}

getEntry 计算 hash 和桶下标,再沿链表查找;匹配则返回节点,否则返回 null。外层 get 返回节点的 value。因此 get(key) == null 可能是 key 不存在,也可能是它映射到 null;需要区分时再检查 containsKey(key)。这两次调用本身不构成并发下的原子操作。

5. Fail-Fast机制

1
2
3
4
5
6
7
8
/**
* The number of times this HashMap has been structurally modified
* Structural modifications are those that change the number of mappings in
* the HashMap or otherwise modify its internal structure (e.g.,
* rehash). This field is used to make iterators on Collection-views of
* the HashMap fail -fast. (See ConcurrentModificationException).
*/
transient int modCount;

HashMap 不是线程安全的。fail-fast 用来发现迭代期间的结构修改,例如通过 map 新增或删除映射;同一个线程在迭代器之外修改 map,也可能触发检查,并不需要另一个线程。仅替换已有 key 的 value 不属于这里的结构修改。

modCount 是普通的 int 字段,不是 volatile,也没有提供同步;transient 只与默认序列化有关,不能保证线程间可见性。迭代器初始化时保存 expectedModCount,后续在 nextEntry() 和 remove() 中比较计数。补上完整的内部迭代器类:

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
private abstract class HashIterator<E> implements Iterator<E> {
Entry<K,V> next; // next entry to return
int expectedModCount; // For fast-fail
int index; // current slot
Entry<K,V> current; // current entry

HashIterator() {
expectedModCount = modCount;
if (size > 0) { // advance to first entry
Entry[] t = table;
while (index < t.length && (next = t[index++]) == null)
;
}
}

public final boolean hasNext() {
return next != null;
}

final Entry<K,V> nextEntry() {
if (modCount != expectedModCount)
throw new ConcurrentModificationException();
Entry<K,V> e = next;
if (e == null)
throw new NoSuchElementException();

if ((next = e.next) == null) {
Entry[] t = table;
while (index < t.length && (next = t[index++]) == null)
;
}
current = e;
return e;
}

public void remove() {
if (current == null)
throw new IllegalStateException();
if (modCount != expectedModCount)
throw new ConcurrentModificationException();
Object k = current.key;
current = null;
HashMap.this.removeEntryForKey(k);
expectedModCount = modCount;
}
}

可以看到,hasNext() 只判断还有没有节点,并不检查计数。迭代器自己的 remove() 删除节点后会更新 expectedModCount,因此这种允许的删除方式不会因为自己刚完成的修改而失败。

注意:fail-fast 只是尽力检测程序错误,不能保证发现所有未同步的并发修改,也不能依赖 ConcurrentModificationException 保证正确性。共享读写必须有适当的同步或并发容器设计;替换 value 不增加计数,也不意味着这类跨线程写入自动安全。

6. 后续 JDK 的变化(2026 年补充)

  • OpenJDK jdk7u80-b15:普通空 map 的构造函数不再直接分配桶数组,table 先指向 EMPTY_TABLE,首次 put 调用 inflateTable。不能把 7u21 的分配时机推广到所有 Java 7 更新版。

  • OpenJDK jdk8-b132:节点改为 Node,碰撞桶可转换为红黑树;TREEIFY_THRESHOLD = 8、MIN_TREEIFY_CAPACITY = 64,但是否树化还取决于插入路径及容量,不能说“第 8 个节点必定树化”。容量不足时先扩容。普通链表扩容按高低两组拆分,并保留各组内的相对次序,已不是本文的迁移头插法。

  • Java SE 19 起的 API:新增 HashMap.newHashMap(expectedMappings),参数是预期映射数量,使用默认加载因子;与构造函数的初始桶容量参数区分。此处按 Java SE 25 API 文档核对。

这些实现变化没有把 HashMap 变成有序或线程安全的容器。阅读现代 JDK 时,应按对应版本的 putVal、resize、treeifyBin 继续追踪;Android 项目还要核对实际平台 API 和 libcore,不能只用编译所选 JDK 的版本推断设备上的行为。

参考

关于我 && 博客

下面是个人的介绍和相关的链接,期望与同行的各位多多交流,三人行,则必有我师!

  1. 博主个人介绍 :里面有个人的微信和微信群链接。
  2. 本博客内容导航 :个人博客内容的一个导航。
  3. 个人整理和搜集的优秀博客文章 - Android 性能优化必知必会 :欢迎大家自荐和推荐 (微信私聊即可)
  4. Android性能优化知识星球:付费社群已于 2026 年停止运营,不再招收新成员;此处保留历史介绍。

一个人可以走的更快 , 一群人可以走的更远
微信扫一扫

CATALOG
  1. 1. 1. HashMap的数据结构:
  2. 2. 2.构造函数
  3. 3. 3.put操作
  4. 4. 4.get操作
  5. 5. 5. Fail-Fast机制
  6. 6. 6. 后续 JDK 的变化(2026 年补充)
  7. 7. 参考
  • 关于我 && 博客